

DP-600 Dumps Special Discount for limited time Try FOR FREE
DP-600 Dumps for success in Actual Exam Sep-2026]
Microsoft DP-600 Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 93
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a lakehouse named Lakehousel. Lakehousel contains a Delta table named Customer.
When you query Customer, you discover that the query is slow to execute. You suspect that maintenance was NOT performed on the table.
You need to identify whether maintenance tasks were performed on Customer.
Solution: You run the following Spark SQL statement:
DESCRIBE DETAIL customer
Does this meet the goal?
- A. No
- B. Yes
Answer: A
Explanation:
The command:
DESCRIBE DETAIL Customer
Returns metadata about the Delta table, such as format, schema, partitioning, size, number of files, and creation/modification timestamps.
However, it does not provide information about whether maintenance tasks (such as OPTIMIZE, VACUUM, or Z-Ordering) were performed on the table.
To check maintenance history, you would typically use:
DESCRIBE HISTORY Customer
which shows operations executed on the table (e.g., OPTIMIZE, VACUUM, MERGE).
Since DESCRIBE DETAIL does not satisfy the requirement, the solution does not meet the goal.
Reference:
DESCRIBE DETAIL in Delta Lake
DESCRIBE HISTORY in Delta Lake
NEW QUESTION # 94
Case Study 2 - Litware, Inc
Overview
Litware, Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
Fabric Environment
Litware has been using a Microsoft Power BI tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Available Data
Litware has data that must be analyzed as shown in the following table.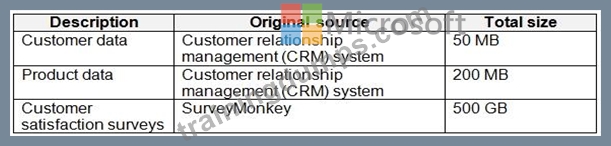
The Product data contains a single table and the following columns.
The customer satisfaction data contains the following tables:
- Survey
- Question
- Response
For each survey submitted, the following occurs:
- One row is added to the Survey table.
- One row is added to the Response table for each question in the survey.
- The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Requirements
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Liware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity The following three workspaces will be created:
- AnalyticsPOC: Will contain the data store, semantic models, reports pipelines, dataflow, and notebooks used to populate the data store
- DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate OneLake
- DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
- A data store (type to be decided)
- A custom semantic model
- A default semantic model
Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest, transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
- Read access by using T-SQL or Python
- Semi-structured and unstructured data
- Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SOL. queries and in the default semantic model. The following logic must be used:
- List prices that are less than or equal to 50 are in the low pricing group.
- List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
- List prices that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC.
Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
- Fabric administrators will be the workspace administrators.
- The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
- The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
- The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook
- The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power BI reports by using the semantic models created by the analytics engineers.
- The date dimension must be available to all users of the data store.
- The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
FabricAdmins: Fabric administrators
- AnalyticsTeam: All the members of the analytics team
- DataAnalysts: The data analysts on the analytics team
- DataScientists: The data scientists on the analytics team
- DataEngineers: The data engineers on the analytics team
- AnalyticsEngineers: The analytics engineers on the analytics team
Report Requirements
The data analysts must create a customer satisfaction report that meets the following requirements:
- Enables a user to select a product to filter customer survey responses to only those who have purchased that product.
- Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected dat.
- Shows data as soon as the data is updated in the data store.
- Ensures that the report and the semantic model only contain data from the current and previous year.
- Ensures that the report respects any table-level security specified in the source data store.
- Minimizes the execution time of report queries.
You need to ensure the data loading activities in the AnalyticsPOC workspace are executed in the appropriate sequence. The solution must meet the technical requirements.
What should you do?
- A. Create and schedule a Spark job definition.
- B. Create a dataflow that has multiple steps and schedule the dataflow.
- C. Create and schedule a Spark notebook.
- D. Create a pipeline that has dependencies between activities and schedule the pipeline.
Answer: D
Explanation:
Pipeline can ensure the activities follow the required sequence.
https://learn.microsoft.com/en-us/fabric/data-factory/activity-overview#data-transformation- activities
NEW QUESTION # 95
You have the following KQL query.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
NEW QUESTION # 96
You have a Fabric tenant that contains a lakehouse named Lakehouse1.
You need to prevent new tables added to Lakehouse1 from being added automatically to the default semantic model of the lakehouse.
What should you configure?
- A. the Lakehouse1 settings
- B. the workspace settings
- C. the semantic model settings
- D. the SQL analytics endpoint settings
Answer: D
Explanation:
You need to prevent new tables added to Lakehouse1 from being added automatically to the default semantic model of the lakehouse.
https://learn.microsoft.com/en-us/fabric/data-warehouse/semantic-models but "Sync the default Power BI semantic model".
NEW QUESTION # 97
You have a Fabric workspace named Workspace1 that contains a dataflow named Dataflow1. Dataflow1 returns 500 rows of data.
You need to identify the min and max values for each column in the query results.
Which three Data view options should you select? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
- A. Show column profile in details pane
- B. Enable details pane
- C. Enable column profile
- D. Show column value distribution
- E. Show column quality details
Answer: A,C,D
NEW QUESTION # 98
Which workspace rote assignments should you recommend for ResearchReviewersGroupl and ResearchReviewersGroupZ? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: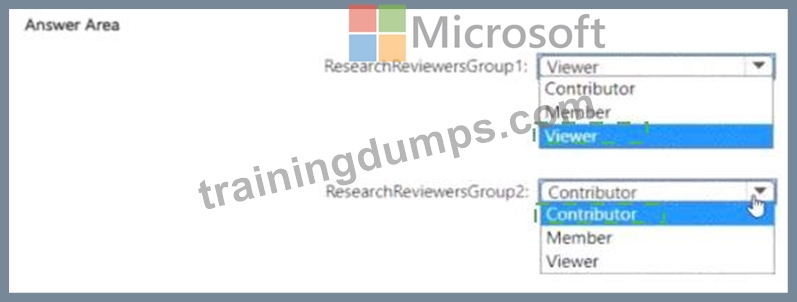
Explanation:
In Azure DevOps workspace (project) security settings, role assignments determine access levels for groups:
Viewer (equivalent to the Readers security group): Grants read-only access to work items, code, pipelines, and other artifacts. Ideal for review-only scenarios where users need to view but not edit content.
Contributor (equivalent to the Contributors security group): Allows full edit and contribute privileges, such as updating work items, code reviews, and pipeline runs. Suitable for active participation in reviews that may involve feedback or changes.
Based on the group names implying review-focused access, Viewer fits Group1 for passive observation, while Contributor fits Group2 for interactive review tasks. These align with default Azure DevOps permissions for secure, least-privilege access.
NEW QUESTION # 99
You have a Fabric tenant that contains a semantic model. The model contains data about retail stores.
You need to write a DAX query that will be executed by using the XMLA endpoint. The query must return the total amount of sales from the same period last year.
How should you complete the DAX expression? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
First blank: CALCULATE
Second blank: _LYSales
Step 1 - Defining the variable
We want to calculate sales for the same period in the prior year. The correct function here is CALCULATE, because it allows applying a filter context modification (with SAMEPERIODLASTYEAR).
So:
VAR _LYSales =
CALCULATE ( [Total Sales], SAMEPERIODLASTYEAR ( 'Orders'[Order Date] ) ) Step 2 - Returning the value We then need to RETURN the value of the variable. From the dropdown options, we select _LYSales.
So:
EVALUATE
VAR _LYSales =
CALCULATE ( [Total Sales], SAMEPERIODLASTYEAR ( 'Orders'[Order Date] ) ) RETURN ROW ( "LastYearSales", _LYSales ) Note: In XMLA DAX queries, you usually need a table expression, so wrapping with ROW or SELECTCOLUMNS is common, but based on the provided answer box, just returning _LYSales is sufficient here.
Final Answer:
First blank: CALCULATE
Second blank: _LYSales
NEW QUESTION # 100
You need to migrate the Research division data for Productline2. The solution must meet the data preparation requirements. How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.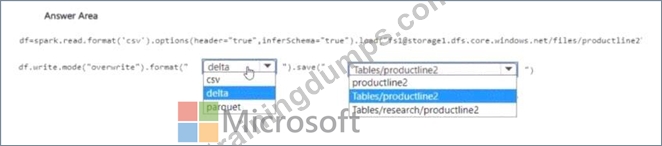
Answer:
Explanation:
Explanation:
Comprehensive Detailed Explanation
From the case study:
Research division data for Productline2 is currently in CSV format in storage2.
Requirement: "All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer." In Fabric lakehouses, managed tables are stored in Delta format inside the Tables folder.
Step 1: Reading the source
df = spark.read. format ( " csv " ) \
options(header= " true " , inferSchema= " true " ) \
load( " abfss://storage1.dfs.core.windows.net/files/productline2 " )
This correctly ingests the CSV source from ADLS Gen2.
Step 2: Writing to Lakehouse as a managed table
You must write the data in Delta format to ensure it is queryable and managed within the lakehouse.
The correct path is under Tables/ , because this is where Fabric automatically manages Lakehouse managed tables .
The target table should be named productline2 , so the correct path is:
df.write.mode( " overwrite " ). format ( " delta " ).save( " Tables/productline2 " ) Why not other options?
CSV or Parquet formats would not create a managed Lakehouse table; they would just create files.
Writing to productline2 directly (without Tables/ ) would store unmanaged files in the Lakehouse Files area, not managed tables.
Writing to Tables/research/productline2 adds an unnecessary subdirectory and is not the standard structure for managed tables.
Correct Final Code
df.write.mode( " overwrite " ). format ( " delta " ).save( " Tables/productline2 " ) References Managed tables in Microsoft Fabric Lakehouse Delta Lake support in Fabric Spark write to Lakehouse
NEW QUESTION # 101
You have a Fabric tenant that contains a warehouse named Warehouse!. Warehousel contains two schemas name schemal and schema2 and a table named schemal.city.
You need to make a copy of schemal.city in schema2. The solution must minimize the copying of data.
Which T-SQL statement should you run?
- A. CREATE TABLE schema2.city AS SELECT * FROM schemal.city;
- B. CREATE TABLE schema2.city AS CLONE OF schemal.city;
- C. SELECT * INTO schema2.eity FROM schemal.city;
- D. INSERT INTO schema2.city SELECT * FROM schemal.city;
Answer: B
Explanation:
INSERT INTO ... SELECT and SELECT INTO both physically copy all rows, which is heavy and not minimal.
CREATE TABLE AS SELECT (CTAS) also copies the data.
CREATE TABLE ... AS CLONE OF creates a shallow clone in Fabric Warehouse, meaning it references the existing data without duplicating it, minimizing storage and copying.
Correct answer: B.
Reference: Clone tables in Fabric warehouse
NEW QUESTION # 102
You need to provide Power Bl developers with access to the pipeline. The solution must meet the following requirements:
* Ensure that the developers can deploy items to the workspaces for Development and Test.
* Prevent the developers from deploying items to the workspace for Production.
* Follow the principle of least privilege.
Which three levels of access should you assign to the developers? Each correct answer presents part of the solution. NOTE: Each correct answer is worth one point.
- A. Build permission to the production semantic models
- B. Contributor access to the Development and Test workspaces
- C. Viewer access to the Production workspace
- D. Admin access to the deployment pipeline
- E. Viewer access to the Development and Test workspaces
- F. Contributor access to the Production workspace
Answer: B,C,D
Explanation:
To meet the requirements, developers should have Admin access to the deployment pipeline (B), Contributor access to the Development and Test workspaces (E), and Viewer access to the Production workspace (D). This setup ensures they can perform necessary actions in development and test environments without having the ability to affect production. Reference = The Power BI documentation on workspace access levels and deployment pipelines provides guidelines on assigning appropriate permissions.
NEW QUESTION # 103
You have a Fabric eventhouse that contains a KQL database. The database contains a table named TaxiData that stores the following data.
You need to create a column named FirstPickupDateTime that will contain the first value of each hour from tpep_pickup_datetime partitioned by payment_type.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
NEW QUESTION # 104
You have source data in a CSV file that has the following fields:
* SalesTra nsactionl D
* SaleDate
* CustomerCode
* CustomerName
* CustomerAddress
* ProductCode
* ProductName
* Quantity
* UnitPrice
You plan to implement a star schema for the tables in WH1. Thedimension tables in WH1 will implement Type 2 slowly changing dimension (SCD) logic.
You need to design the tables that will be used for sales transaction analysis and load the source data.
Which type of target table should you specify for the CustomerName, CustomerCode, and SaleDate fields?
To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
CC
Answer:
Explanation:
Explanation:
We are designing a star schema for sales transactions. In a star schema:
Dimension tables contain descriptive attributes (e.g., Customer, Product, Date).
Fact tables contain measurable, quantitative data (e.g., SalesTransactionID, Quantity, UnitPrice).
Factless fact tables capture events without numeric measures.
Junk dimensions store miscellaneous low-cardinality attributes.
The requirement says dimension tables will use Type 2 Slowly Changing Dimensions (SCD) # so Customer and Date attributes belong to Dimension tables.
Field-by-field classification
CustomerCode
A business key (natural key) for the customer dimension.
Belongs in the Customer Dimension table.
The Answer:
Dimension.
CustomerName
A descriptive attribute of the customer.
Belongs in the Customer Dimension table.
The Answer:
Dimension.
SaleDate
A time attribute used for analysis.
Belongs in the Date Dimension table.
The Answer:
Dimension.
Final Answer:
CustomerCode # Dimension
CustomerName # Dimension
SaleDate # Dimension
References:
Star schema design for Power BI / Fabric
Slowly Changing Dimensions in data warehousing
# This follows Kimball's star schema best practices.
NEW QUESTION # 105
You have a Fabric tenant that contains a warehouse.
Several times a day, the performance of all warehouse queries degrades. You suspect that Fabric is throttling the compute used by the warehouse.
What should you use to identify whether throttling is occurring?
- A. the Monitoring hub
- B. dynamic management views (DMVs)
- C. the Capacity settings
- D. the Microsoft Fabric Capacity Metrics app
Answer: D
NEW QUESTION # 106
You have a Fabric eventhouse named Eventhousel that contains a table named Weatherdata. A sample of the data in Weatherdata is shown in the following table.
You plan to use a KQL queryset to manipulate the data in Eventhouse1. The result set must have the following columns.
You need to build the query.
Which four KQL statements should you use in sequence? To answer, move the appropriate statements from the list of statements to the answer area and arrange them in the correct order.
Answer:
Explanation: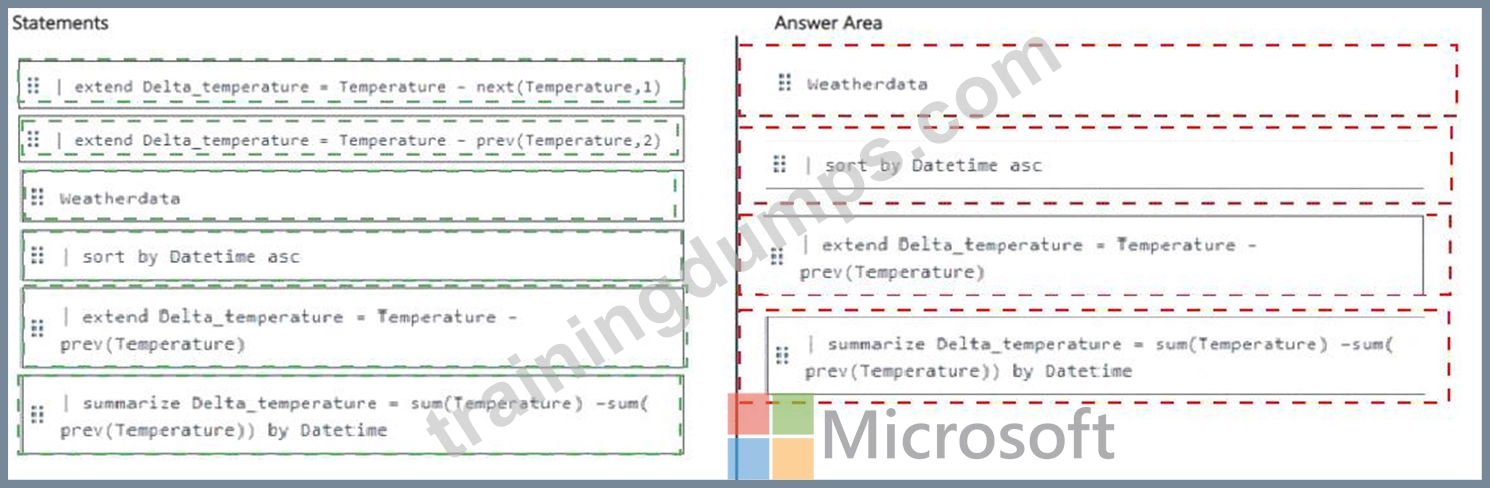
Explanation:
NEW QUESTION # 107
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.
You need to reduce the execution time of the query.
Solution: You replace line 4 by using the following code:
Does this meet the goal?
- A. No
- B. Yes
Answer: A
Explanation:
The suggested replacement does not improve performance. COUNTROWS( ' Order Item ' ) < 0 is always false (row counts cannot be negative), so the NOT will always evaluate to true. This means the filter condition becomes non-selective and would return all customers, not just those with orders. Therefore, it does not meet the optimization goal.
NEW QUESTION # 108
You have a Fabric workspace named Workspace1 that contains a data flow named Dataflow1. Dataflow1 contains a query that returns the data shown in the following exhibit.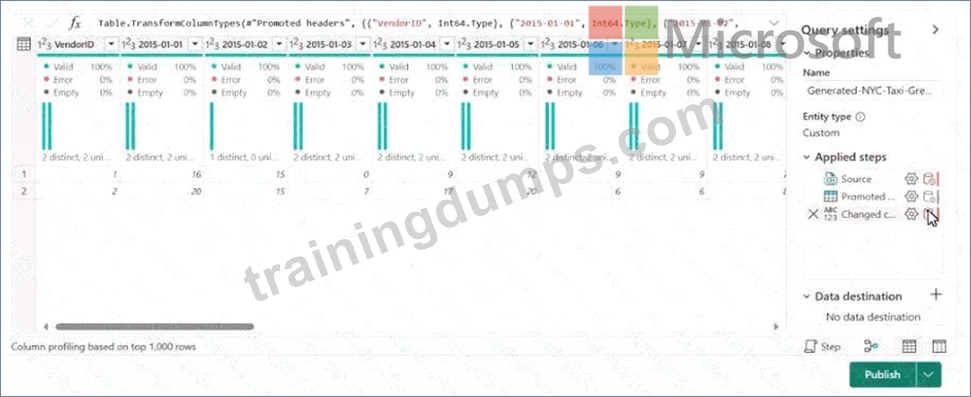
You need to transform the date columns into attribute-value pairs, where columns become rows.
You select the VendorlD column.
Which transformation should you select from the context menu of the VendorlD column?
- A. Remove other columns
- B. Unpivot other columns
- C. Split column
- D. Group by
- E. Unpivot columns
Answer: B
Explanation:
The transformation you should select from the context menu of the VendorID column to transform the date columns into attribute-value pairs, where columns become rows, is Unpivot columns (B). This transformation will turn the selected columns into rows with two new columns, one for the attribute (the original column names) and one for the value (the data from the cells). References = Techniques for unpivoting columns are covered in the Power Query documentation, which explains how to use the transformation in data modeling.
NEW QUESTION # 109
You are creating a semantic model in Microsoft Power BI Desktop.
You plan to make bulk changes to the model by using the Tabular Model Definition Language (TMDL) extension for Microsoft Visual Studio Code.
You need to save the semantic model to a file.
Which file format should you use?
- A. PBIX
- B. PBIDS
- C. PBIP
- D. PBIT
Answer: C
Explanation:
The PBIP will create one file and two folders, PBIP.Dataset contains definition folder that is use to host the .tmdl files.
NEW QUESTION # 110
......
Accurate DP-600 Answers 365 Days Free Updates: https://vcecollection.trainingdumps.com/DP-600-valid-vce-dumps.html
