Databricks Certified Associate Developer for Apache Spark 3.5 - Python VCE dumps for simulated practice
Except the pdf files, the Databricks Certified Associate Developer for Apache Spark 3.5 - Python VCE dumps are popular and welcome in the choosing of the IT candidates. If you want to experience the VCE format, you can select the Databricks Certified Associate Developer for Apache Spark 3.5 - Python pc test engine and online test engine as you like. In fact, Databricks Certification Associate-Developer-Apache-Spark-3.5 VCE dump is a test simulator, which can bring you into a virtual real test environment. The interaction and intelligent properties of Databricks Certified Associate Developer for Apache Spark 3.5 - Python VCE format training have attracted many candidates, and motivate the enthusiastic for study of the Databricks Associate-Developer-Apache-Spark-3.5 actual test. You can get scores after each test, and can set each test time as you like with the Databricks Certified Associate Developer for Apache Spark 3.5 - Python VCE test engine. Besides, you can install it on your electric device and practice it at your convenience. Thus your spare time will be made full use of. With the simulated test engine, you can re-practice your test until you are sure to pass it. In addition, our Databricks Certified Associate Developer for Apache Spark 3.5 - Python VCE test engine is virus-free engine, so you can rest assured to install it on your device.
Dear every one, trust our Databricks Certified Associate Developer for Apache Spark 3.5 - Python training collection, you will get a high score in your first try.
Databricks Associate-Developer-Apache-Spark-3.5 Dumps Instant Download: Upon successful payment, Our systems will automatically send the product you have purchased to your mailbox by email. (If not received within 12 hours, please contact us. Note: don't forget to check your spam.)
Maybe you are a hard-work person who has spent much time on preparing for Associate-Developer-Apache-Spark-3.5 exam test. While the examination fee is very expensive, you must want to pass at your first try. Databricks Certified Associate Developer for Apache Spark 3.5 - Python pdf vce dumps will provide you everything you will need to take for your actual test. The content of Associate-Developer-Apache-Spark-3.5 exam test are researched and produced by our senior experts who have rich hands-on experience in IT industry. The precise and logical are the requirement during the edition for Databricks Certified Associate Developer for Apache Spark 3.5 - Python free demo torrent. From our Databricks Certification study training, you will get knowledge different from books. Our Databricks Certified Associate Developer for Apache Spark 3.5 - Python actual test dumps will help you not only pass in the first try, but also save your valuable time and energy. Now hurry up to get a boost in your career and get your Databricks Certified Associate Developer for Apache Spark 3.5 - Python certification.

Original Questions and Verified Answers
Get the original questions and verified answers for your preparation about Databricks Certified Associate Developer for Apache Spark 3.5 - Python training dumps, and 100% pass is the guarantee of our promise. We put the interest of customers in the first place. So in order to meet the needs of our customer, we strive for making the best valid and accurate Databricks Certified Associate Developer for Apache Spark 3.5 - Python exam prep collection for all of you, and ensure you pass at first attempt with less time and energy investment. The Databricks Certification Associate-Developer-Apache-Spark-3.5 questions are compiled from the original questions and checked and edited by our experienced experts. As we all know, it is not enough to ensure 100% pass just by the simulated questions, the accurate answers are very necessary for successful pass. While our Databricks Certified Associate Developer for Apache Spark 3.5 - Python dumps prep answers can satisfy your requirement. The question answers are verified by vast data analysis and checked by several processes, thus the high hit rate can be possible. Choose our Databricks Certified Associate Developer for Apache Spark 3.5 - Python free download training, you will not only gain a high test score, but also a broad spectrum of knowledge.
Databricks Associate-Developer-Apache-Spark-3.5 Exam Syllabus Topics:
| Section | Objectives |
|---|---|
| Topic 1: Spark SQL | - Window functions and aggregations - SQL queries on DataFrames and tables |
| Topic 2: Data Ingestion and Storage | - Delta Lake basics - Reading and writing data (Parquet, JSON, CSV) |
| Topic 3: Apache Spark Fundamentals | - Spark architecture and execution model - RDD vs DataFrame vs Dataset concepts |
| Topic 4: Structured Streaming Basics | - Streaming DataFrames - Windowed aggregations in streaming |
| Topic 5: Data Processing and Performance | - Caching and persistence strategies - Joins and data partitioning - Optimization techniques |
| Topic 6: DataFrame API with PySpark | - Built-in functions and expressions - DataFrame creation and schema management - Transformations and actions |
Databricks Certified Associate Developer for Apache Spark 3.5 - Python Sample Questions:
31 of 55.
Given a DataFrame df that has 10 partitions, after running the code:
df.repartition(20)
How many partitions will the result DataFrame have?
- A. Same number as the cluster executors
- B. 5
- C. 20
- D. 10
Correct Answer: C 🗳️
Explanation: Only visible for TrainingDumps members. You can sign-up / login (it's free).
What is the benefit of using Pandas on Spark for data transformations?
Options:
- A. It executes queries faster using all the available cores in the cluster as well as provides Pandas's rich set of features.
- B. It is available only with Python, thereby reducing the learning curve.
- C. It computes results immediately using eager execution, making it simple to use.
- D. It runs on a single node only, utilizing the memory with memory-bound DataFrames and hence cost-efficient.
Correct Answer: A 🗳️
Explanation: Only visible for TrainingDumps members. You can sign-up / login (it's free).
Given a DataFrame df that has 10 partitions, after running the code:
result = df.coalesce(20)
How many partitions will the result DataFrame have?
- A. Same number as the cluster executors
- B. 20
- C. 1
- D. 10
Correct Answer: D 🗳️
Explanation: Only visible for TrainingDumps members. You can sign-up / login (it's free).
An engineer has two DataFrames: df1 (small) and df2 (large). A broadcast join is used:
python
CopyEdit
from pyspark.sql.functions import broadcast
result = df2.join(broadcast(df1), on='id', how='inner')
What is the purpose of using broadcast() in this scenario?
Options:
- A. It reduces the number of shuffle operations by replicating the smaller DataFrame to all nodes.
- B. It filters the id values before performing the join.
- C. It increases the partition size for df1 and df2.
- D. It ensures that the join happens only when the id values are identical.
Correct Answer: A 🗳️
Explanation: Only visible for TrainingDumps members. You can sign-up / login (it's free).
A data scientist wants each record in the DataFrame to contain:
The first attempt at the code does read the text files but each record contains a single line. This code is shown below: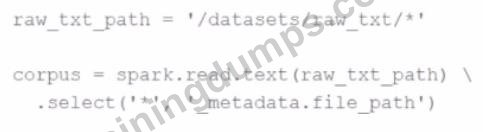
The entire contents of a file
The full file path
The issue: reading line-by-line rather than full text per file.
Code:
corpus = spark.read.text("/datasets/raw_txt/*") \
.select('*', '_metadata.file_path')
Which change will ensure one record per file?
Options:
- A. Add the option wholetext=False to the text() function
- B. Add the option lineSep='\n' to the text() function
- C. Add the option lineSep=", " to the text() function
- D. Add the option wholetext=True to the text() function
Correct Answer: D 🗳️
Explanation: Only visible for TrainingDumps members. You can sign-up / login (it's free).


 Jeff

 Gabriel

 Humphrey

 Nick
 York
 Murphy
 Ben
 Vita
 Jacob
 Jeremy
 Karen